SEO and visibility · SEO and visibility
Technical SEO: the essential basics
A helpful website can only fulfil its purpose if people and search engines can access its content. Technical SEO creates the necessary foundations: pages must respond reliably, serve important content clearly and send unambiguous signals about how they should be processed. This is not a collection of secret settings, but careful work on your existing website.
This guide explains the key relationships and shows which errors deserve attention first. You do not need to be able to implement every technical concept yourself. What matters is being able to interpret issues, ask the right questions and verify corrections clearly. Good technology makes access easier, but guarantees neither indexing nor good positions.
From a page request to a possible search result
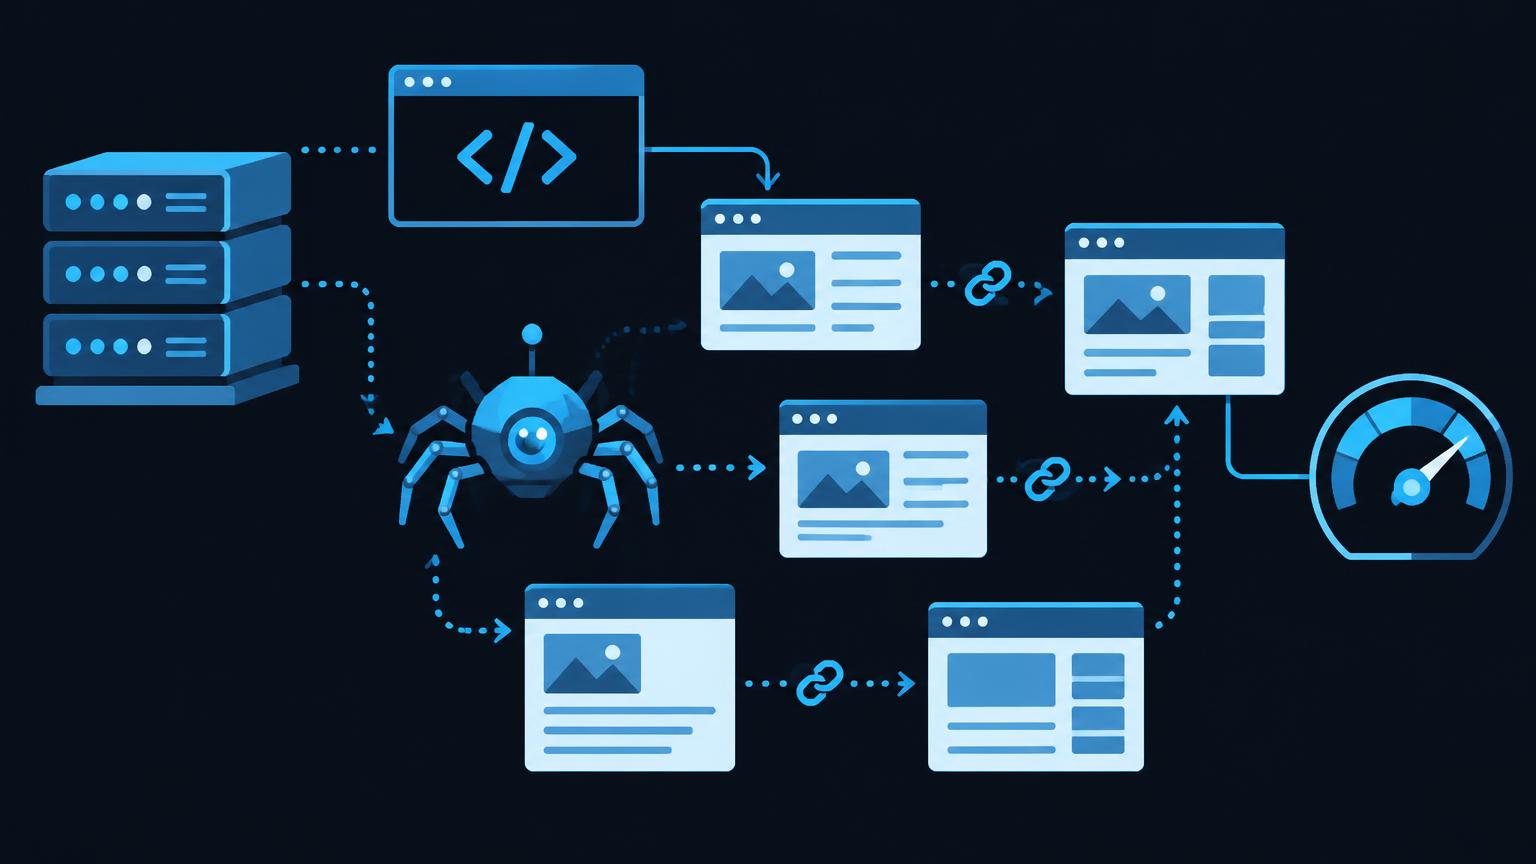
When a browser or crawler requests an address, the server responds with a status code and, where applicable, content. A crawler is an automated program that fetches accessible pages. During the subsequent rendering process, additional resources and JavaScript may be needed to produce the visible content. You should consider these steps separately.
Indexing means that a search system adds the processed content to its index. Only then can relevant search results be generated from it. The graphic deliberately shows this path without any guarantee of success. A successful retrieval is an important prerequisite, but does not prove that a page will actually be indexed or appear for a particular query.
When problems arise, first check where the process is being interrupted. Is the server failing to respond? Is the text missing after rendering? Is indexing excluded? Or is the page technically accessible but failing to address the search intent? The general basics of SEO help you distinguish technical causes from content-related ones.
robots.txt and noindex have different roles
The robots.txt file sits in a host's root directory and controls which areas particular crawlers may fetch. It is not access protection or a reliable tool for removing an address from search results. According to Google's introduction to robots.txt, a blocked address may still appear as an address in search results under certain circumstances.
The noindex directive, by contrast, asks supporting search engines not to index a page. It can be served, for example, as a meta directive in the HTML or as an HTTP header. For Google to recognise it, the page concerned must be accessible for retrieval. Blocking crawling at the same time can therefore prevent Google from seeing the directive at all.
Private content requires genuine access protection, such as a login. Neither noindex nor robots.txt replaces this protection. After a relaunch, check particularly carefully whether blocks from the test environment have accidentally remained on public service pages. Conversely, private previews must not rely solely on voluntary compliance by search engines.
Canonicals and XML sitemaps: organise addresses clearly
The same content can be accessible at several addresses, for example because of parameters or different URL variants. A canonical signals which address you consider the preferred version. It is not a command that Google must follow. Conflicting signals make this association harder, for example when internal links point to a different version from the canonical.
Google describes the methods in its documentation on specifying canonical URLs. Define a clear primary address for each important piece of content. In particular, check whether templates accidentally point all subpages to the homepage. This pattern can incorrectly consolidate content on different subjects.
An XML sitemap lists important addresses in a machine-readable format. It makes discovery easier but does not guarantee indexing. Include the intended public primary versions and remove addresses that have been deleted or deliberately excluded. The sitemap replaces neither clear navigation nor internally linked service pages. Content, links and technical information should be consistent.
Status codes, redirects and error pages
A status code describes the server's response. 200 usually indicates a successful retrieval. 404 means that the requested resource was not found, while 410 identifies a resource that is no longer available. Errors in the 500 range indicate server-side problems. What matters is the actual response, not just the visible design.
A permanent redirect can be implemented with 301 or 308. Other codes, such as 302 or 307, are available for temporary situations. Choose behaviour that matches what is actually happening. When moving a page, the old address should lead as directly as possible to the corresponding new content, rather than through several intermediate steps.
Not every removed page needs a redirect. If there is no suitable replacement, a correct error response may make sense. An attractive error page with status 200, however, can result in a so-called soft 404. Do not simply redirect every unknown address to the homepage. Also check internal links so that visitors are less likely to land on outdated addresses in the first place.
Mobile presentation, HTTPS and clear URLs
Important content must remain usable on small screens too. Check navigation, forms, tables and contact options as well as body text. A mobile layout is not good simply because it becomes visually narrower. Missing text or hidden controls can make a site significantly harder to use. The article on responsive web design complements this review.
HTTPS protects transmission between browser and server through encryption. It replaces neither secure passwords nor system security. Make sure the certificate is valid and important resources are not loaded over insecure connections. When consolidating variants, redirects, internal links and preferred addresses must be consistent.
A clear URL structure helps with maintenance and navigation. Choose stable, meaningful paths and avoid unnecessary variants for the same content. Do not change existing addresses simply because another version supposedly looks better. Every change requires a plan for redirects and links. Internal links should lead directly to accessible destination pages and describe their content clearly.
Interpreting loading speed and Core Web Vitals correctly
Long waits can hinder visitors, particularly on mobile connections. Check large images, unnecessary scripts, blocking resources and the server's response time. However, a single measurement does not tell you how every real visit feels. The device, connection, cache and page state can affect the result. Repeatable test conditions help you assess improvements objectively.
The Core Web Vitals on web.dev describe three important aspects: Largest Contentful Paint measures when the largest visible content element appears, Interaction to Next Paint measures responsiveness to interactions, and Cumulative Layout Shift measures unexpected layout shifts. The metrics answer different questions and should not be reduced to a single overall quality score.
Good values are LCP of up to 2.5 seconds, INP of up to 200 milliseconds and CLS of up to 0.1. The 75th percentile is used to assess real-user data. Lab measurements from a test and field data from actual visits provide different perspectives. If a page does not have enough field data, this is not evidence of either a good or a poor user experience.
Turn a finding into a specific task: reserve space for images, reduce unnecessary scripts or serve the most important image appropriately. Before implementation, check which resources are genuinely needed. Do not remove features without assessing them simply to improve a test score. Good measurements do not guarantee a good search position.
Request a technical website analysis to assess important obstacles and suitable next steps.
Send a non - binding enquiryChecking JavaScript and structured data systematically
Modern websites generate some content with JavaScript. This is not inherently problematic, but it requires checking. Content visible in the browser may be missing if required scripts or interfaces are inaccessible. Check whether important text and links are present in the processed view and whether errors prevent loading.
Important internal links should be implemented as genuine links with a clear destination. A button that only performs a local action does not automatically replace an easily discoverable page link. Also avoid making core service information accessible only after interactions that are difficult to follow. People and search systems need a clear route to relevant content.
Structured data describes content in a standardised format. The information must match the visible content and be factually correct. Error-free markup alone does not guarantee an enhanced search appearance. Before implementation, check whether a particular type is supported and suitable for your content. The article on structured data explains this distinction in more detail.
A technical review with clear questions
Start with representative pages: the homepage, key services, a guide and a contact page. For larger websites, include different templates. This makes it easier to see whether an error affects just one address or is a systematic issue in a shared template. The number of reported issues alone tells you nothing about their business significance.
| Technical area | Possible issue | Effect | Checking tool |
|---|---|---|---|
| Indexing | Unintended noindex | Page is instructed not to appear in the index | URL Inspection and source code |
| Server response | Error or redirect chain | Retrieval is hindered or interrupted | Browser network panel |
| Canonical | Reference to an unsuitable primary address | Conflicting association | Source code and URL Inspection |
| Mobile use | Hidden navigation | Important areas are difficult to access | Browser with a narrow viewport |
| Loading behaviour | Late content or layout shifts | The site is harder to use | PageSpeed Insights |
| JavaScript | Service copy is missing after processing | Key information is unavailable | Rendered view and console |
For each finding, add the affected addresses, the expected behaviour and verifiable evidence. This allows a specialist to work on specific issues rather than having to interpret a general error list. The website analysis puts findings like these into context; subsequent website improvement should include specific tasks and follow-up checks.
Interactive example: explore clearly explained checks
In the sample technical assessment, you can open neutral checks covering accessibility, indexing, redirects and presentation. Each point explains what an issue might mean and which follow-up check makes sense. The sequence is designed to help you identify fundamental obstacles before cosmetic improvements.
This demo does not scan a real website. It does not check a domain, retrieve server responses or issue an actual assessment result. The examples are for explanatory purposes. To answer the same questions about your own site, you need access to the website and suitable measurement data.
Prioritise, fix and follow up with Search Console
First prioritise errors that completely block important content or incorrectly exclude public pages. Next come incorrect associations, problematic redirects and major usability issues. A minor issue on an unimportant old page has a different significance from the same error across every service page. Consider reach, business relevance and effort together.
Search Console supports follow-up checks with indexing reports and inspection of individual URLs. Reports may take time to reflect changes. Compare the current technical response with the stored information and document when the correction was made. A successful live test does not replace establishing which version has already been processed.
Checklist for technical sign - off
- Important public pages respond with the intended status code.
- Private content is secured by genuine access protection.
- robots.txt and noindex do not conflict with the intended purpose.
- Canonicals, the sitemap and internal links indicate consistent primary addresses.
- Redirects lead directly to relevant content.
- Mobile navigation and forms remain usable.
- Important text and links are present after processing.
- Loading problems are assessed using suitable lab measurements and available field data.
- Corrections and follow-up checks are documented for each finding.
Technical SEO remains a recurring task, particularly after additions or a relaunch. At the same time, a technically sound site is no substitute for helpful content. To establish well-founded priorities, you can request a technical website analysis. You can also find the key relationships at the start of the article.
Summary
- Crawling, rendering and indexing are different steps.
- robots.txt controls retrieval; noindex is no substitute for access protection.
- Canonicals, the sitemap and internal links should be consistent.
- Status codes and redirects must reflect the actual content.
- Mobile usability and loading behaviour are part of technical quality checks.
- Good technology does not guarantee indexing or good positions.
Frequently asked questions
Does robots.txt reliably prevent indexing?
No, robots.txt primarily controls crawling. A blocked address may still appear in search results under certain circumstances. Private content needs genuine access protection.
Why might noindex remain ineffective even when written correctly?
Google must be able to retrieve the directive. If a crawling block prevents access, the directive may go undetected. Check how the settings interact.
Is a canonical a binding directive?
No, it signals the preferred version of a piece of content. Google may select a different address. Consistent internal links and other appropriate signals help establish a clear association.
Does every deleted page need a redirect?
No, if there is no suitable replacement, a correct 404 or 410 response may make sense. If corresponding new content exists, consider an appropriate redirect. Redirecting all errors indiscriminately to the homepage is not a sound solution.
Do good Core Web Vitals guarantee better rankings?
No, good measurements do not guarantee positions. They help assess certain aspects of the user experience. Relevant and helpful content remains necessary too.
Is JavaScript inherently unsuitable for SEO?
No, reliable processing is what matters. Important content and links must be accessible and correctly present after rendering. Check specifically for errors in scripts or required resources.
Sources
- Search Engine Optimisation (SEO) Starter Guide: The Basics | Google Search Central | Documentation | Google for DevelopersGoogle · checked on 2026 - 11 - 05
- Introduction and Guide to robots.txt Files | Google Search Central | Documentation | Google for DevelopersGoogle · checked on 2026 - 11 - 05
- Specify a Canonical URL with rel="canonical" and Other Methods | Google Search Central | Documentation | Google for DevelopersGoogle · checked on 2026 - 11 - 05
- Web Vitals | Articles | web.devGoogle / web.dev · checked on 2026 - 11 - 05
Back to the top of the article